★ 89 stars on GitHub and counting. Yozh Crawler + Scraper is free, open-source, and built in public — give us a star if it earns its place in your stack.
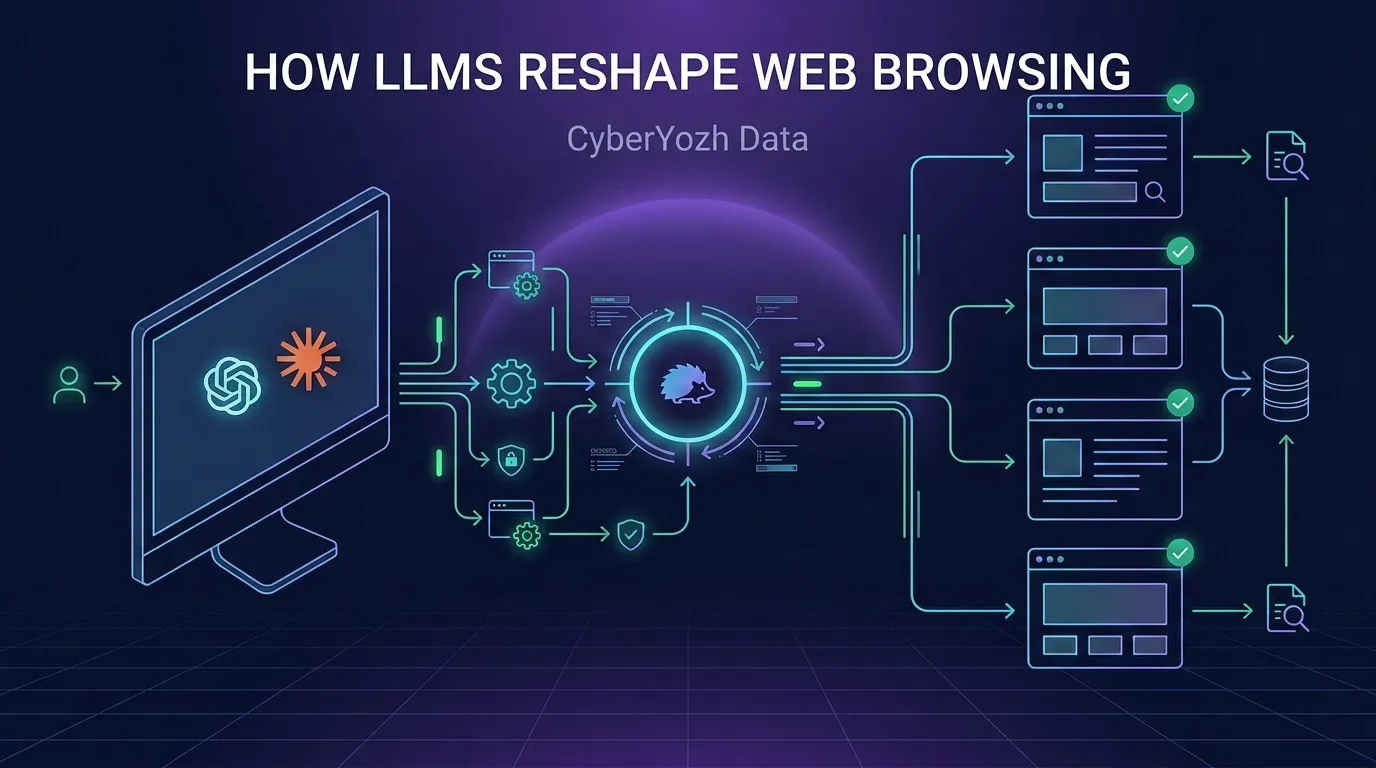
Browse AI: How LLMs Reshape Web Browsing
9 Min Read
AL Alex onSeptember 28, 2026

Browse AI: How LLMs Reshape Web Browsing

AI web browsing turns a normal browser into an assistant that reads pages, clicks buttons, and fills forms for you. Instead of manually repeating the same steps, you describe the task once, and an AI agent handles the rest. See how it works, and why proxies, as always, are needed here.  Spoiler: without them, your […]
Roman onSeptember 24, 2026

Mobile vs. Residential Proxies: Which IP Type Wins for Data Extraction

Selecting the optimal IP infrastructure directly shapes your project architecture. Writing flawless Python code…

Mobile vs. Residential Proxies: Which IP Type Wins for Data Extraction 9 Min Read
Roman onSeptember 23, 2026

Post-Quantum TLS: The New Bot Detection Standard

Content delivery networks now evaluate the cryptographic handshake rather than relying on cookies or…

Post-Quantum TLS: The New Bot Detection Standard 7 Min Read
Alex onSeptember 22, 2026

How to Set Up eBay Scraper with CyberYozh

For compliant regional testing and approved data workflows, an eBay proxy gives you control…

How to Set Up eBay Scraper with CyberYozh 8 Min Read
AL Alex onSeptember 15, 2026

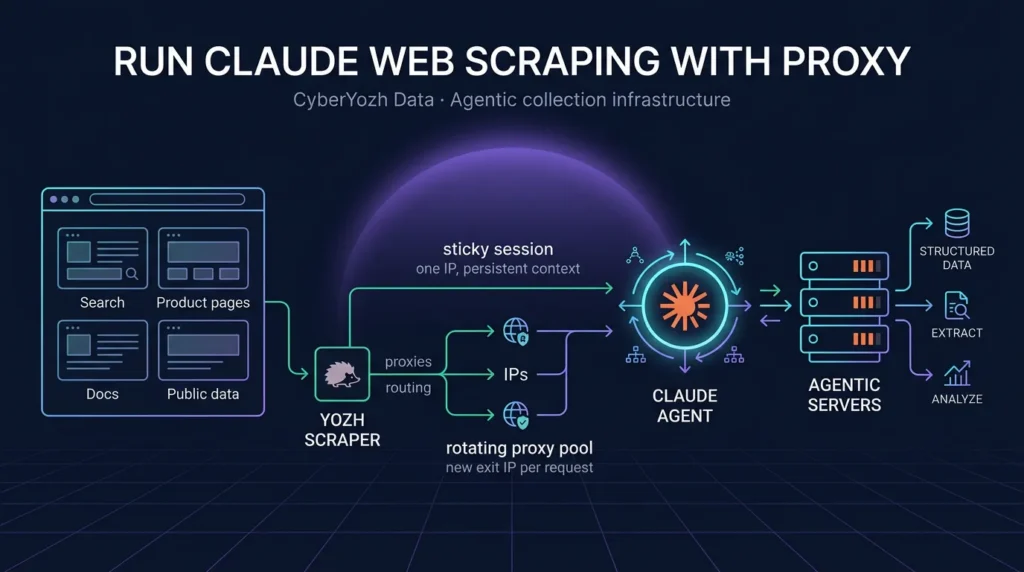
Run Claude Web Scraping with Proxy

Claude web scraping combines an AI assistant with a normal data-collection stack. However, Claude does not replace a browser, HTTP client, or proxy network. Instead, it helps define what data matters, generate and improve extraction logic, explain errors, and transform collected page content into a consistent format.  Key idea: Claude is the reasoning and extraction […]

Discover More
RO Roman onSeptember 10, 2026

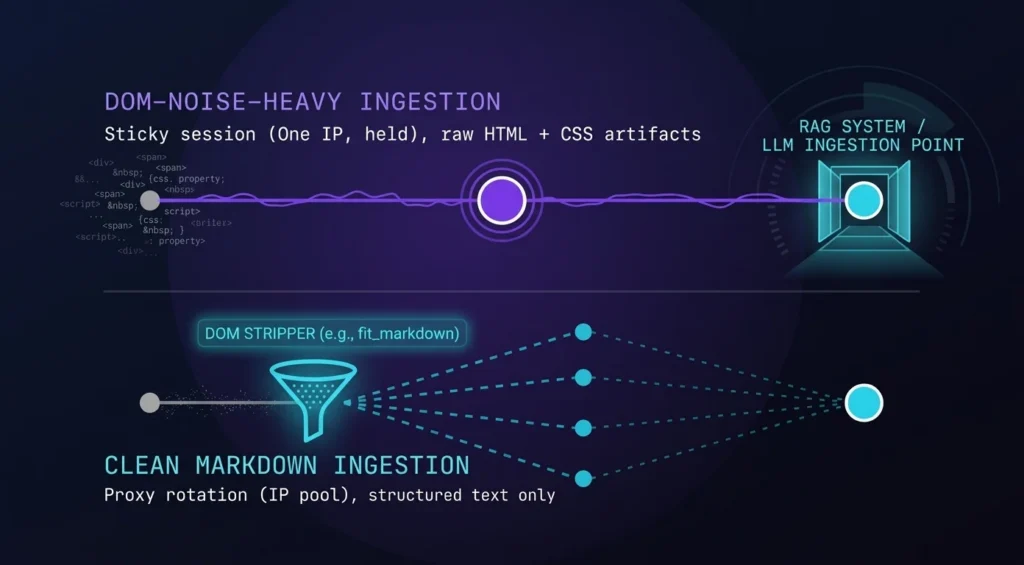
Feeding RAG Systems at Scale: How to Strip DOM Noise and Rotate Proxies for Clean LLM Ingestion

Targeting modern websites to train AI models breaks traditional data extraction pipelines. You point a headless browser at a dynamic product catalog. The target server instantly analyzes your TLS Client Hello signature. It checks your HTTP/2 frame sequence before sending a single byte of data. If your connection lacks a robust proxy ecosystem for web […]

Discover More
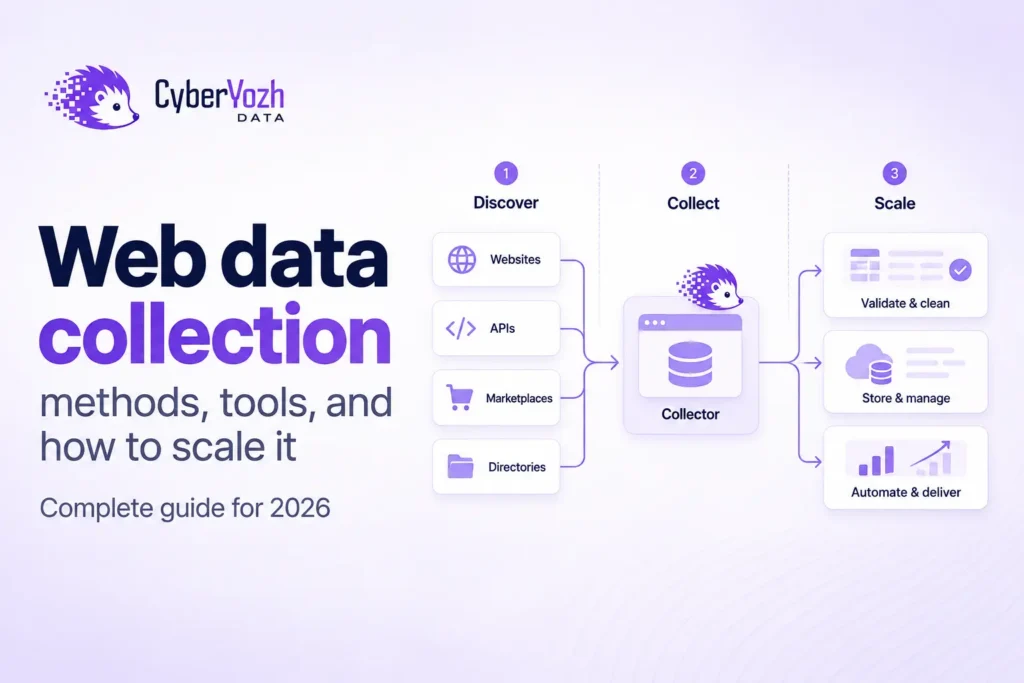
Web data collection in 2026: Methods, tools, and how to scale it
10 Min Read
RO Roman onSeptember 7, 2026

Web data collection in 2026: Methods, tools, and how to scale it

Learn how web data collection works, which methods fit different websites, what tools you need, and how to automate reliable collection at scale.

Discover More
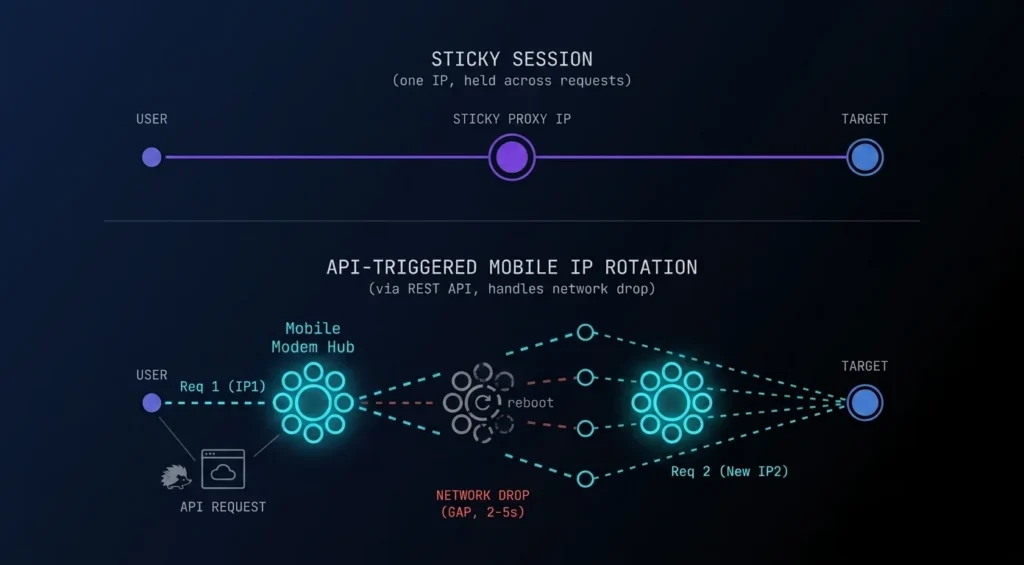
Automated Web Scraping with Python: Handling Mobile IP Rotation via REST API Requests
9 Min Read
RO Roman onSeptember 4, 2026

Automated Web Scraping with Python: Handling Mobile IP Rotation via REST API Requests

TL;DR: Overcoming browser bottlenecks Browser automation carries massive computational overhead. Headless browsers consume gigabytes of RAM. They render unnecessary DOM elements. They spike CPU usage during simple data extraction tasks. Data engineers eventually hit hard scaling limits when running hundreds of Selenium or Playwright instances. Moving your logic directly to HTTP-level scripts solves this hardware […]

Discover More
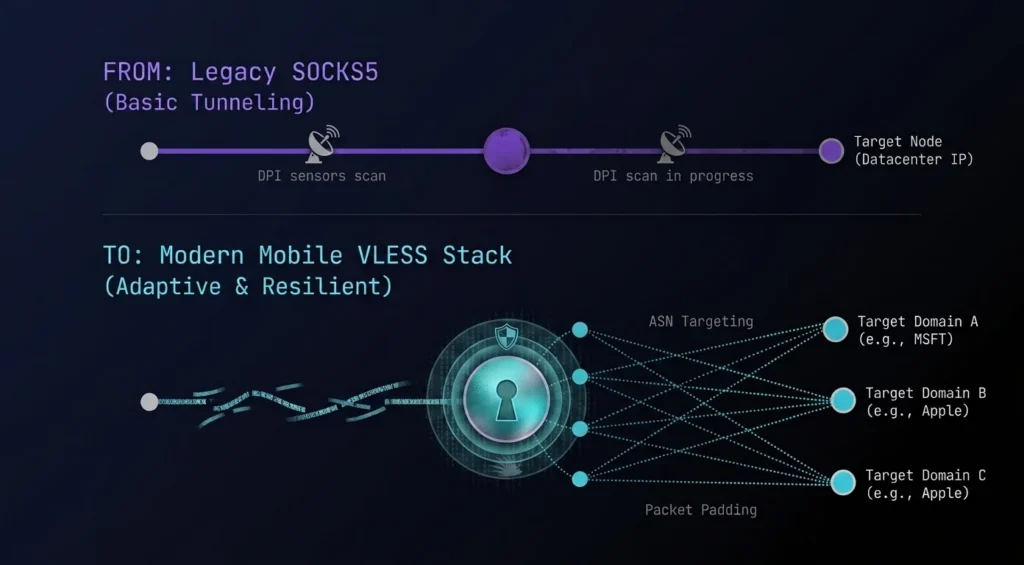
Network Infrastructure Evolution 2026: From Basic SOCKS5 to Mobile VLESS, XHTTP, and XTLS-Reality Networks
8 Min Read
RO Roman onSeptember 3, 2026

Network Infrastructure Evolution 2026: From Basic SOCKS5 to Mobile VLESS, XHTTP, and XTLS-Reality Networks

The SOCKS5 protocol remains a reliable industry standard. It works perfectly in trusted corporate networks. However, under strict DPI filtering from local internet providers, pure SOCKS5 becomes vulnerable. Monitoring systems recognize its signatures. Connections drop. Businesses lose revenue. Data engineers require additional layers of security. Enterprise VLESS proxy infrastructure for data collection solves this. A […]

Discover More
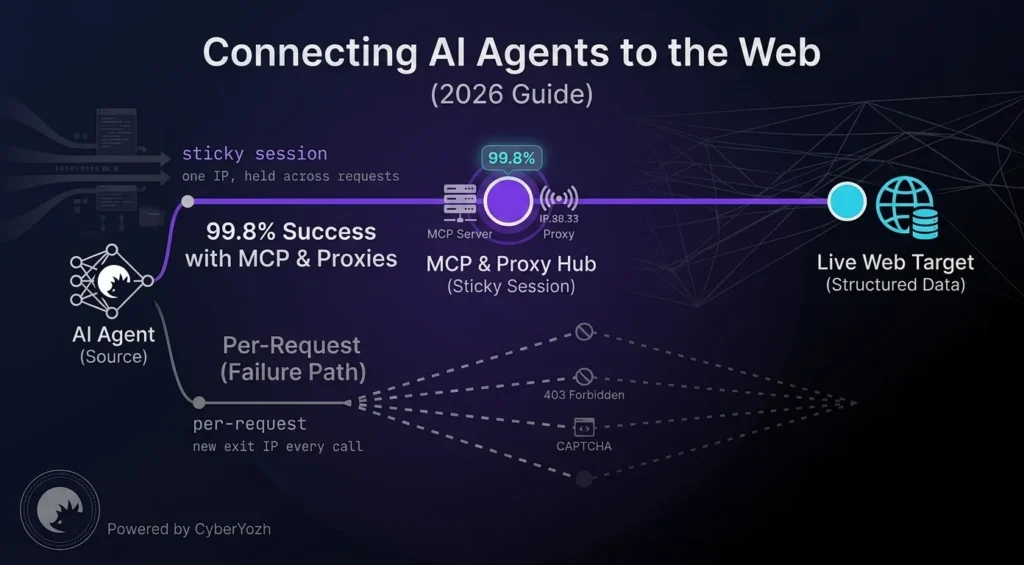
Connecting AI Agents to the Web: 99.8% Success with MCP Servers & Proxies (2026)
5 Min Read
RO Roman onAugust 26, 2026

Connecting AI Agents to the Web: 99.8% Success with MCP Servers & Proxies (2026)

Quick Answer: The Model Context Protocol (MCP) acts as a universal bridge, allowing AI agents (like Claude Desktop or Cursor) to navigate the live web, render JavaScript, and extract structured data. However, to prevent IP bans and CAPTCHAs during automated web crawling, AI agents must route their requests through high-trust residential or mobile proxies that […]

Discover More