★ 90 stars on GitHub and counting. Yozh Crawler + Scraper is free, open-source, and built in public — give us a star if it earns its place in your stack.

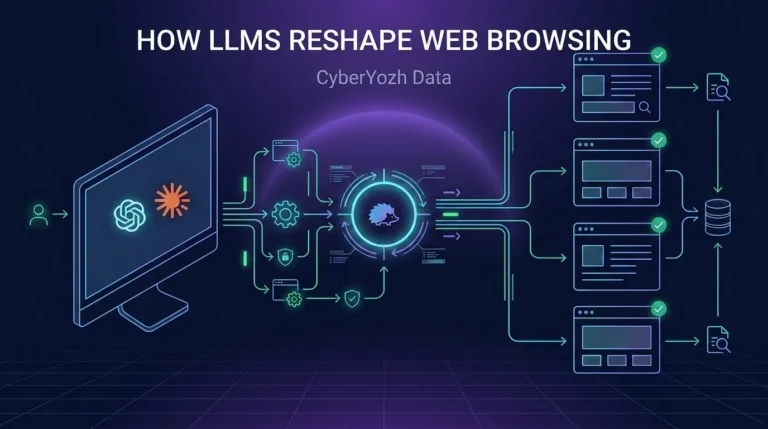
Browse AI: How LLMs Reshape Web Browsing

AI web browsing turns a normal browser into an assistant that reads pages, clicks buttons, and fills forms for you. Instead of manually repeating the same steps, you describe the task once, and an AI agent handles the rest. See how it works, and why proxies, as always, are needed here.  Spoiler: without them, your […]
ebay scraping work

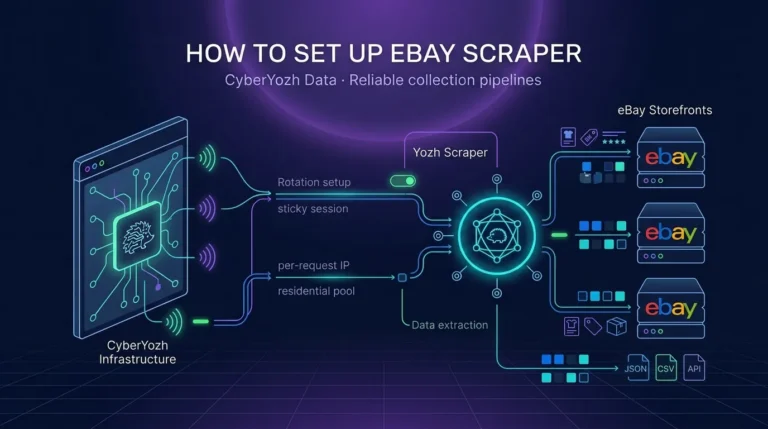
How to Set Up eBay Scraper with CyberYozh

For compliant regional testing and approved data workflows, an eBay proxy gives you control over the connection location and session behavior. A proxy is infrastructure, not permission to bypass marketplace rules, rate limits, or access controls. ℹ️ An eBay scraper can support research workflows such as price comparison, catalog monitoring, and analysis of your own […]

claude web scraping cover

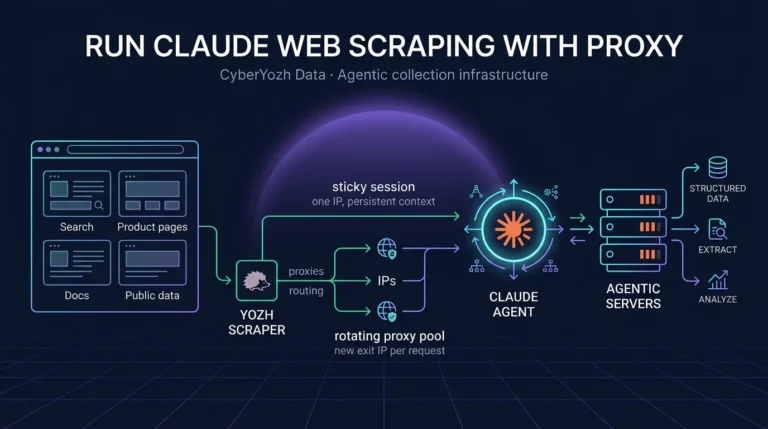
Run Claude Web Scraping with Proxy

Claude web scraping combines an AI assistant with a normal data-collection stack. However, Claude does not replace a browser, HTTP client, or proxy network. Instead, it helps define what data matters, generate and improve extraction logic, explain errors, and transform collected page content into a consistent format.  Key idea: Claude is the reasoning and extraction […]