


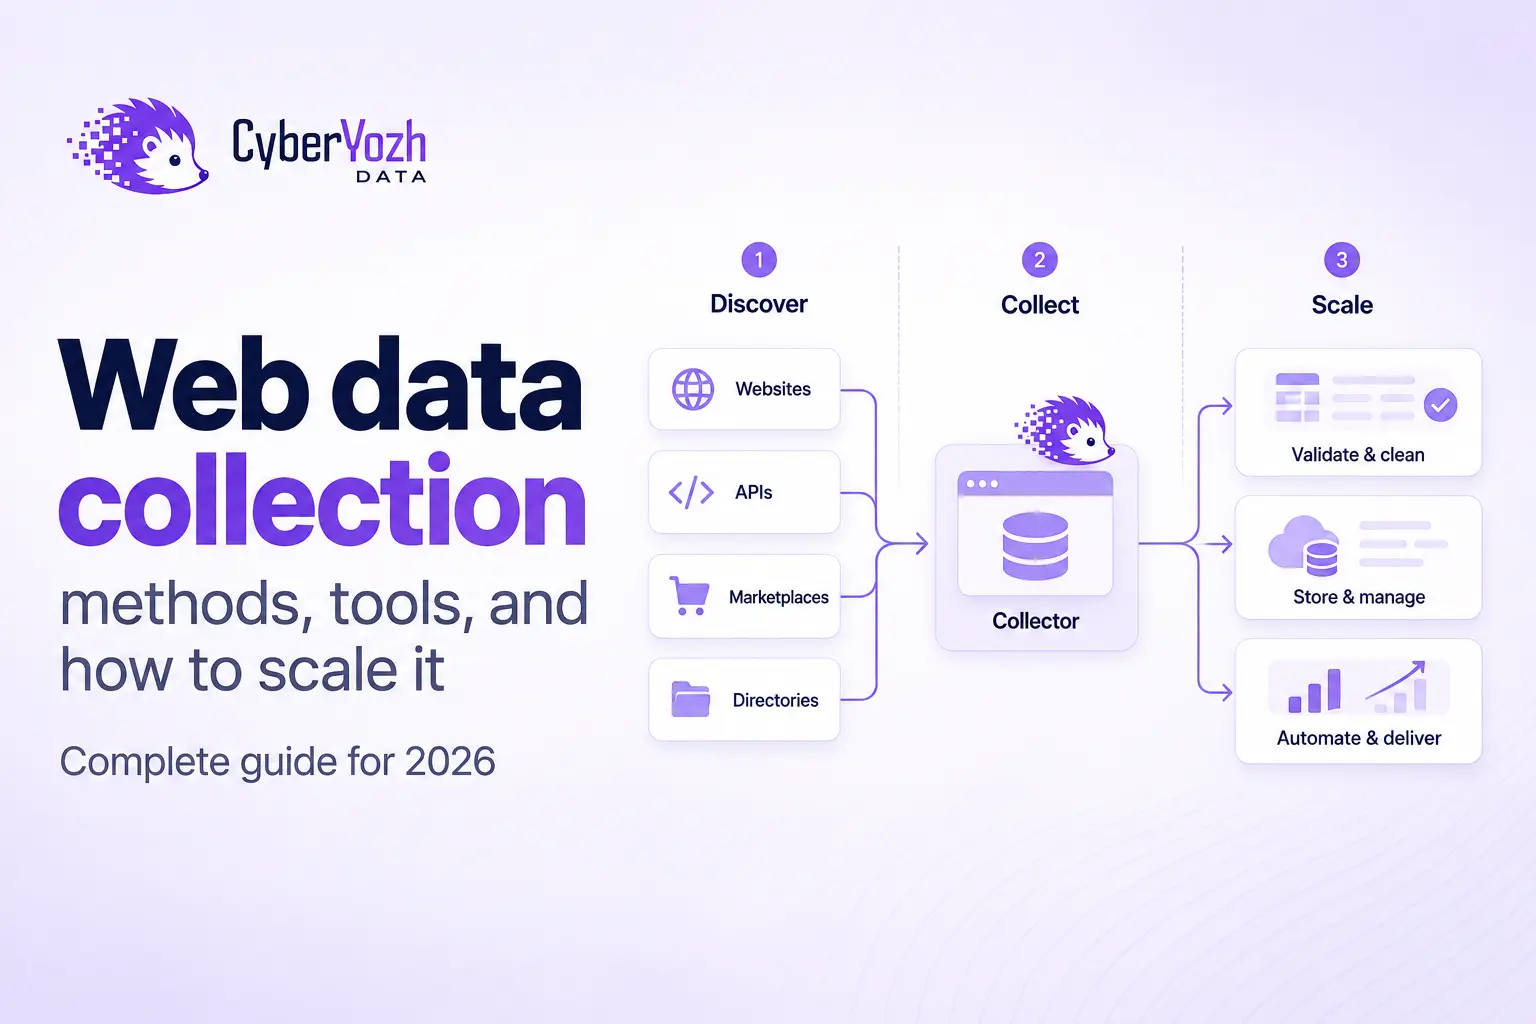
Web data collection in 2026: Methods, tools, and how to scale it
Learn how web data collection works, which methods fit different websites, what tools you need, and how to automate reliable collection at scale.
Learn how web data collection works, which methods fit different websites, what tools you need, and how to automate reliable collection at scale.
TL;DR: Overcoming browser bottlenecks Browser automation carries massive computational overhead. Headless browsers consume gigabytes…
 9 Min Read
The SOCKS5 protocol remains a reliable industry standard. It works perfectly in trusted corporate…
 8 Min Read
Quick Answer: The Model Context Protocol (MCP) acts as a universal bridge, allowing AI…
 5 Min Read
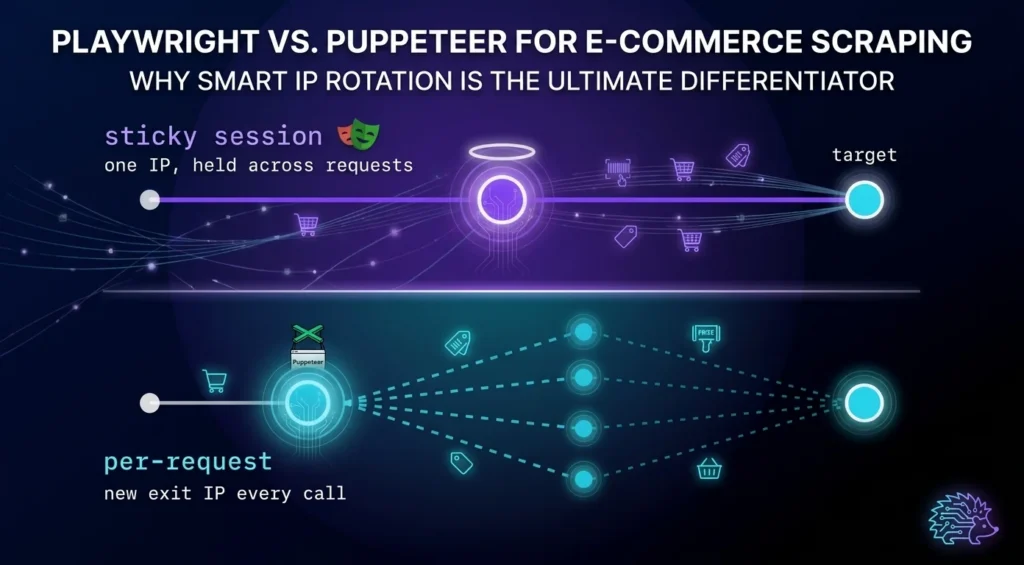
When evaluating Playwright vs Puppeteer for e-commerce scraping, engineers often obsess over execution speed and API syntax. However, in 2026, the landscape of data extraction has fundamentally shifted. Target websites deploy aggressive behavioral analysis, TLS fingerprinting, and dynamic DOM mutations. Building a pipeline that survives these defenses requires far more than picking a browser automation […]
Discover More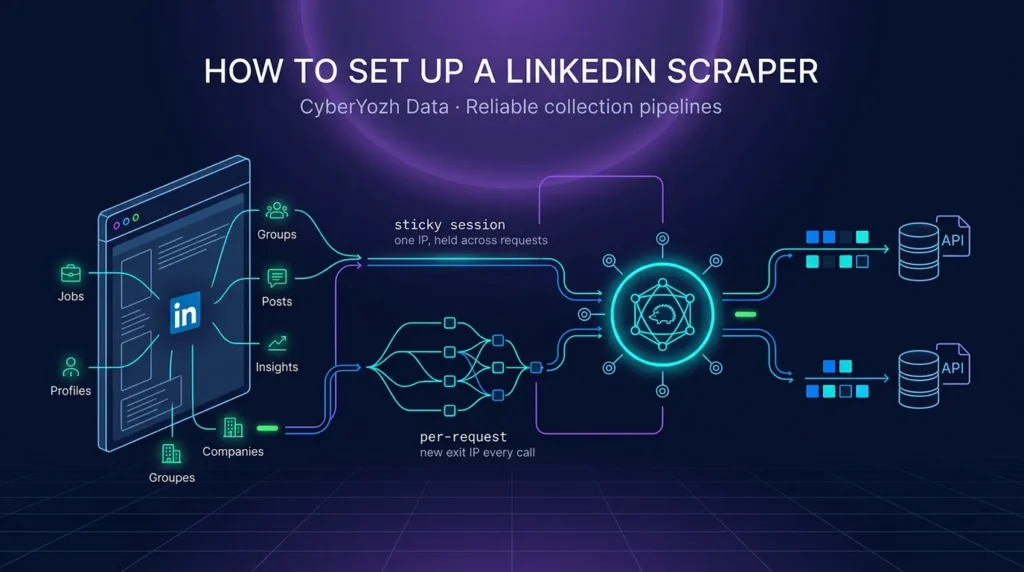
A LinkedIn scraper lets you get profiles, jobs, emails, posts, companies, and other essential business data. The platform is designed to bring business specialists together, and you may find tons of useful data here. CyberYozh infrastructure helps you get this data quickly and efficiently, so you can use it instantly in your business workflows, whether […]
Discover More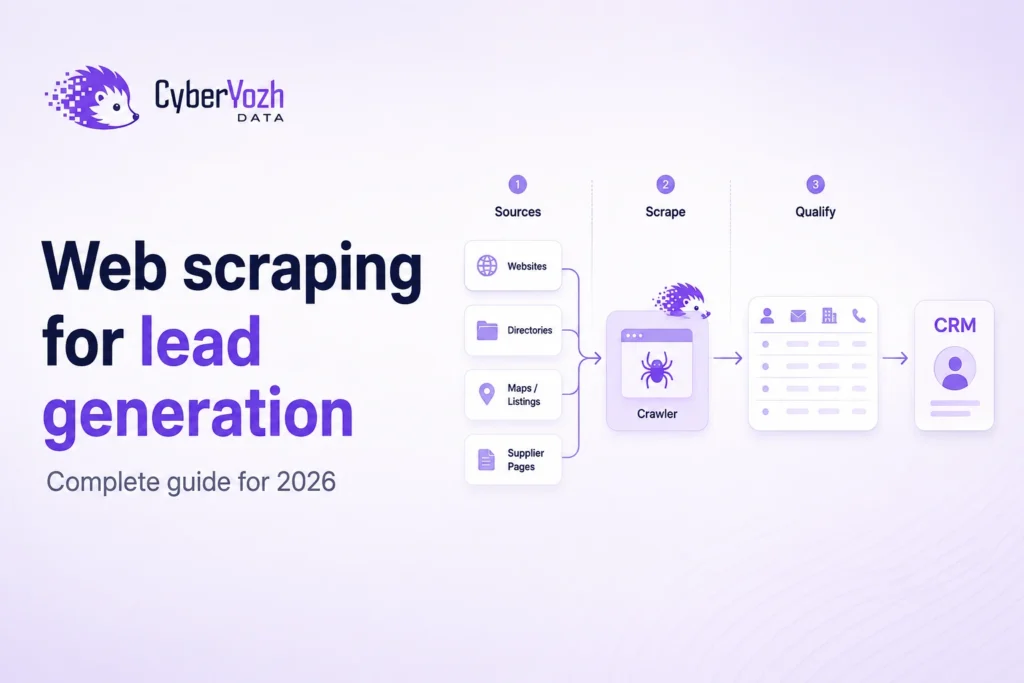
A practical guide to building a reliable lead generation web scraping workflow, from finding public business data to crawling, extraction, validation, proxy selection, and CRM-ready output.
Discover More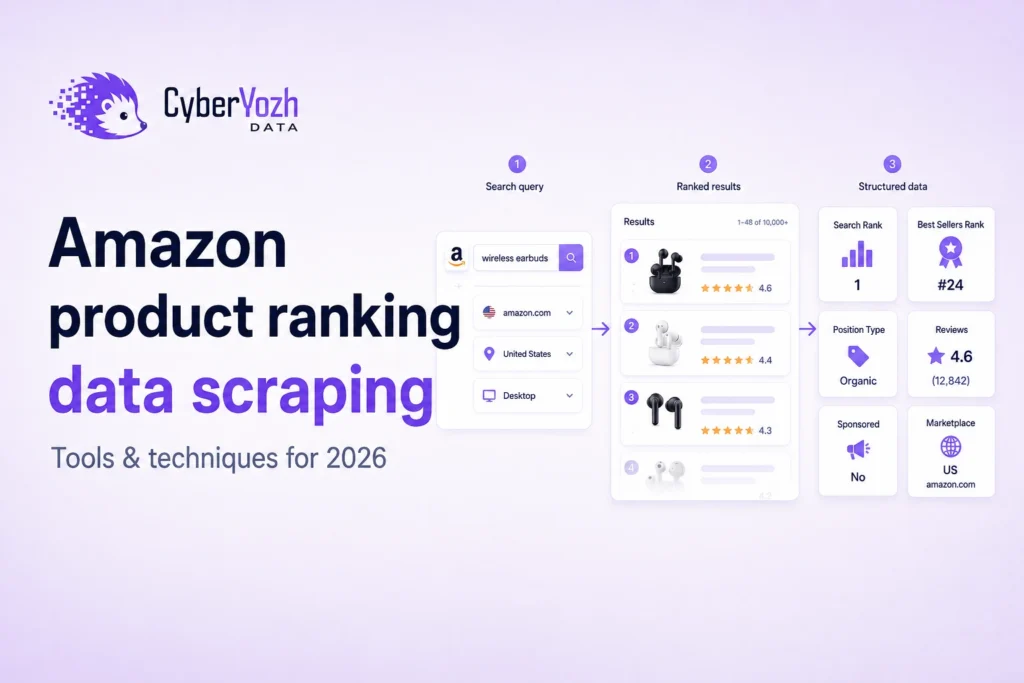
A practical guide to collecting Amazon search rankings, Best Sellers Rank, reviews, prices, and competitor data with CyberYozh Data while preserving marketplace, location, timestamp, and ranking context.
Discover MoreData extraction is the foundational layer of modern artificial intelligence development, market intelligence, and competitive analysis. However, building reliable data pipelines remains an engineering bottleneck. Target websites continuously deploy structural mutations, A/B testing, and dynamic obfuscation, causing rigid extraction scripts to fail. To resolve this paradigm of fragility, the web scraping ecosystem requires a fundamental […]
Discover More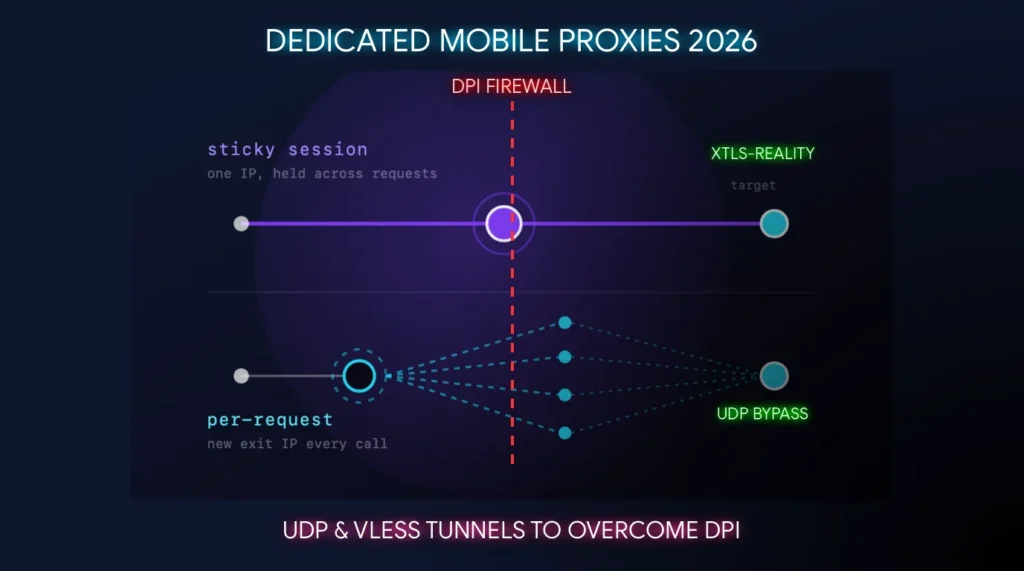
Deep packet inspection (DPI) systems actively scan and drop standard VPN connections. OpenVPN and WireGuard fail within minutes. Because they rely on static headers. Commercial firewalls now analyze byte entropy and packet timing using flow-based machine learning models. They run aggressive active probing routines. You need a resilient architecture. It will protect your network footprint […]
Discover More