★ 89 stars on GitHub and counting. Yozh Crawler + Scraper is free, open-source, and built in public — give us a star if it earns its place in your stack.

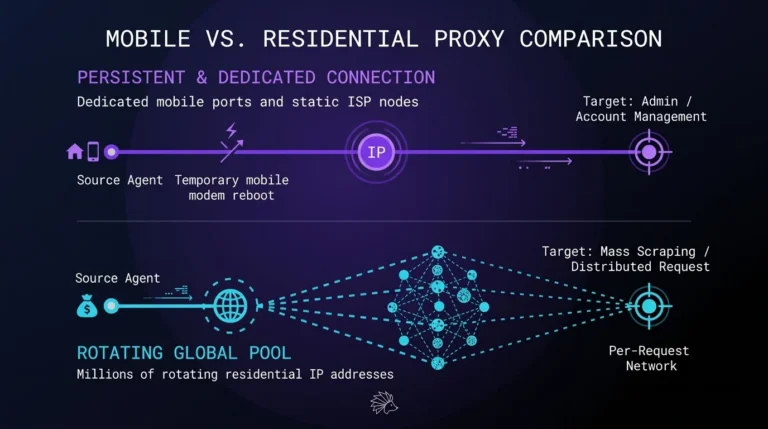
Mobile vs. Residential Proxies: Which IP Type Wins for Data Extraction

Selecting the optimal IP infrastructure directly shapes your project architecture. Writing flawless Python code cannot compensate for a network footprint that contradicts your application data. Modern filtering algorithms analyze the transport layer alongside standard browser headers. Datacenter addresses provide massive throughput for public platforms, but highly protected networks require different solutions. Engineers continuously evaluate mobile […]
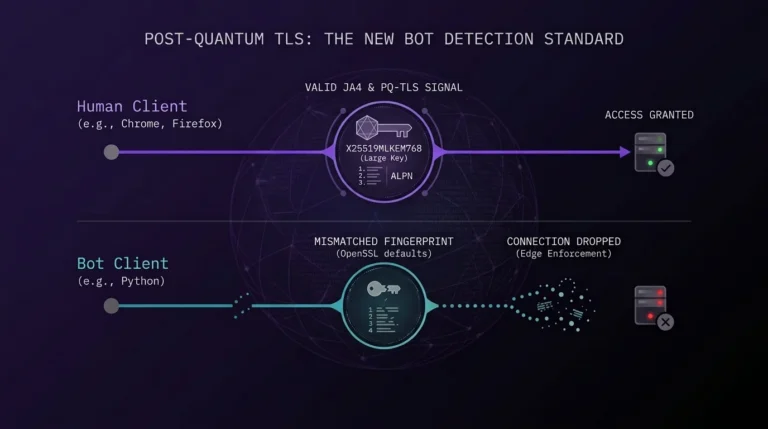
Post-Quantum TLS: The New Bot Detection Standard

Content delivery networks now evaluate the cryptographic handshake rather than relying on cookies or rotating user agents. Modern edge nodes inspect the exact sequence of bytes in the initial connection request long before the client transmits an HTTP payload. If the cryptographic math misaligns with standard Chrome or Firefox behavior, the server simply drops the […]

ebay scraping work

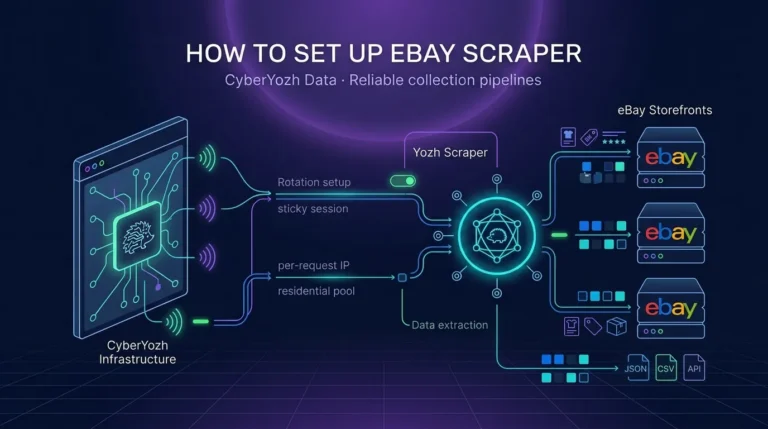
How to Set Up eBay Scraper with CyberYozh

For compliant regional testing and approved data workflows, an eBay proxy gives you control over the connection location and session behavior. A proxy is infrastructure, not permission to bypass marketplace rules, rate limits, or access controls. ℹ️ An eBay scraper can support research workflows such as price comparison, catalog monitoring, and analysis of your own […]

claude web scraping cover

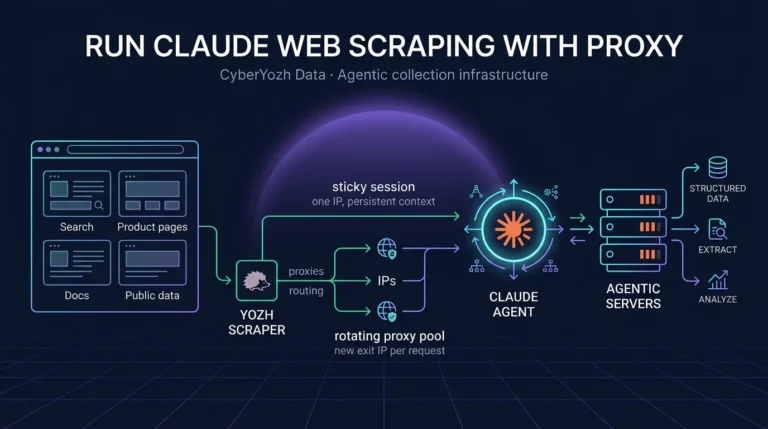
Run Claude Web Scraping with Proxy

Claude web scraping combines an AI assistant with a normal data-collection stack. However, Claude does not replace a browser, HTTP client, or proxy network. Instead, it helps define what data matters, generate and improve extraction logic, explain errors, and transform collected page content into a consistent format.  Key idea: Claude is the reasoning and extraction […]

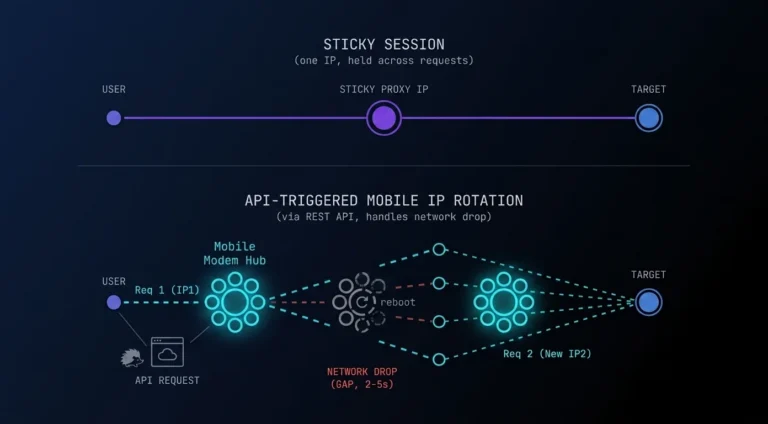
Automated Web Scraping with Python: Handling Mobile IP Rotation via REST API Requests

TL;DR: Overcoming browser bottlenecks Browser automation carries massive computational overhead. Headless browsers consume gigabytes of RAM. They render unnecessary DOM elements. They spike CPU usage during simple data extraction tasks. Data engineers eventually hit hard scaling limits when running hundreds of Selenium or Playwright instances. Moving your logic directly to HTTP-level scripts solves this hardware […]

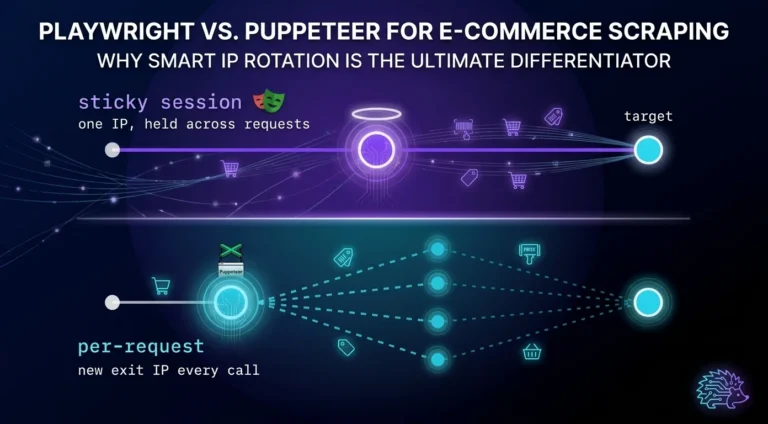
Playwright vs. Puppeteer for E-commerce Scraping: Why Smart IP Rotation is the Ultimate Differentiator

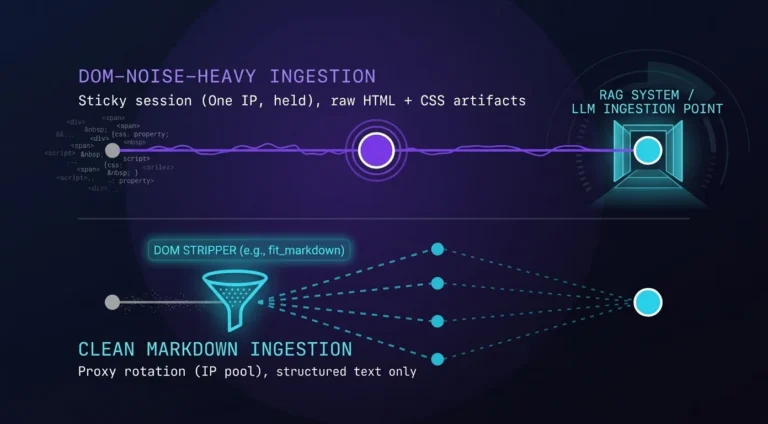
When evaluating Playwright vs Puppeteer for e-commerce scraping, engineers often obsess over execution speed and API syntax. However, in 2026, the landscape of data extraction has fundamentally shifted. Target websites deploy aggressive behavioral analysis, TLS fingerprinting, and dynamic DOM mutations. Building a pipeline that survives these defenses requires far more than picking a browser automation […]

CyberYozh's LinkedIn Scraper

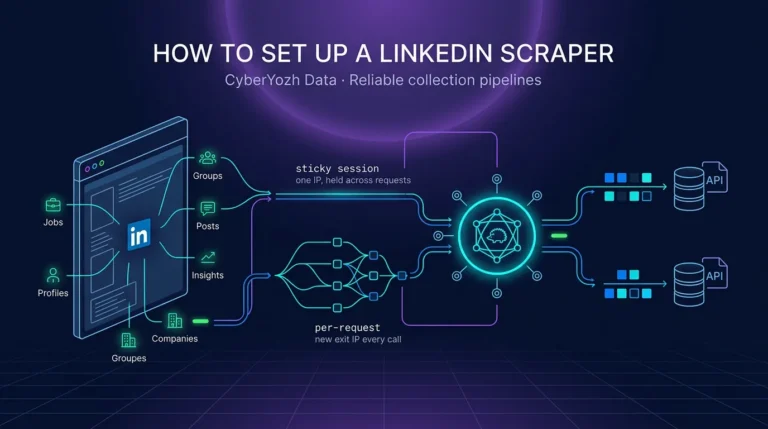
How to Set Up a LinkedIn Scraper

A LinkedIn scraper lets you get profiles, jobs, emails, posts, companies, and other essential business data. The platform is designed to bring business specialists together, and you may find tons of useful data here. CyberYozh infrastructure helps you get this data quickly and efficiently, so you can use it instantly in your business workflows, whether […]