★ 90 stars on GitHub and counting. Yozh Crawler + Scraper is free, open-source, and built in public — give us a star if it earns its place in your stack.
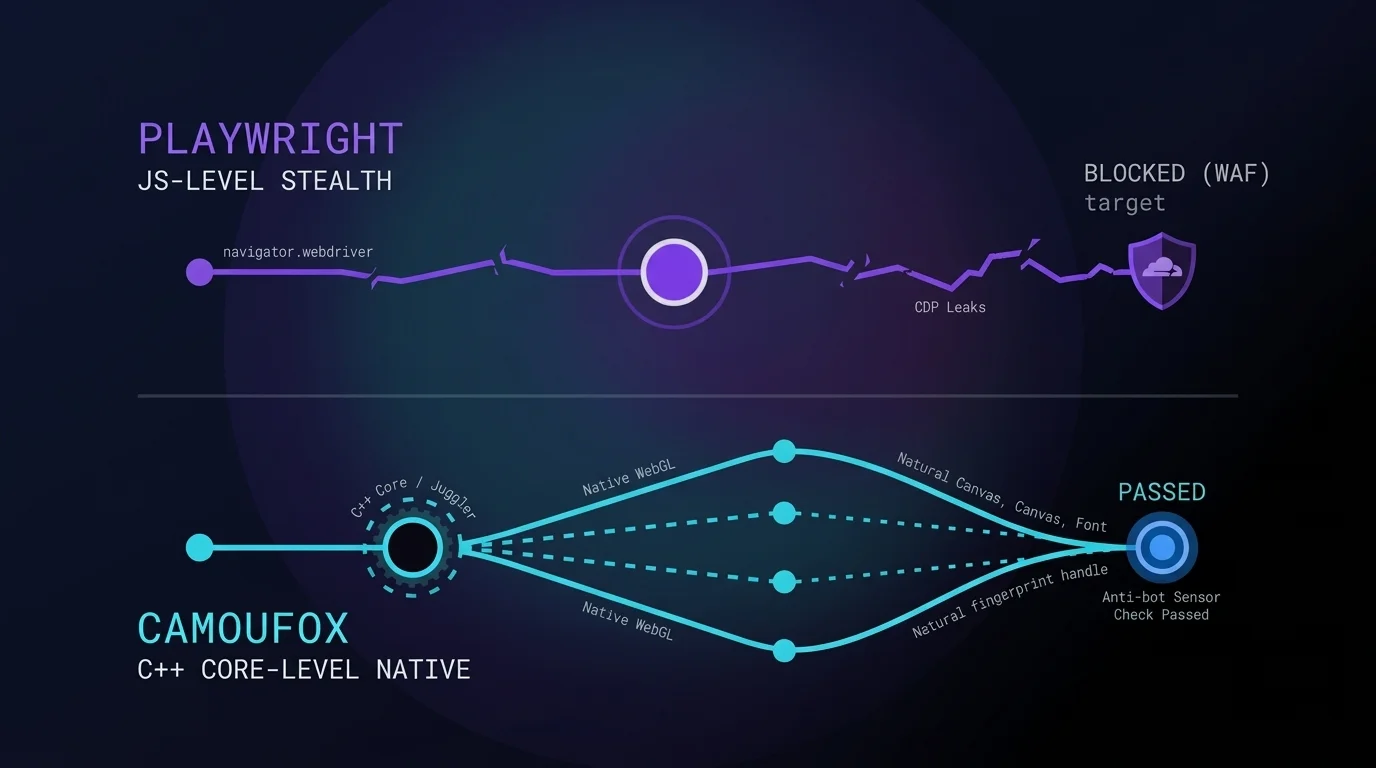
Playwright vs Camoufox: The Future of Anti-Detect Browser Automation
6 Min Read
RO Roman onOctober 1, 2026

Playwright vs Camoufox: The Future of Anti-Detect Browser Automation

Data extraction security has changed. In 2026, Cloudflare and DataDome do not rely on basic user-agent parsing. These platforms evaluate behavioral biometrics alongside structural TLS fingerprinting (JA4). Defense algorithms also probe the environment for JavaScript tampering. Traditional JavaScript patches fail. Engineers need an anti detect browser scraping solution embedded directly at the engine’s source code […]
Alex onSeptember 28, 2026

Browse AI: How LLMs Reshape Web Browsing

AI web browsing turns a normal browser into an assistant that reads pages, clicks…

Browse AI: How LLMs Reshape Web Browsing 9 Min Read
Roman onSeptember 24, 2026

Mobile vs. Residential Proxies: Which IP Type Wins for Data Extraction

Selecting the optimal IP infrastructure directly shapes your project architecture. Writing flawless Python code…

Mobile vs. Residential Proxies: Which IP Type Wins for Data Extraction 9 Min Read
Roman onSeptember 23, 2026

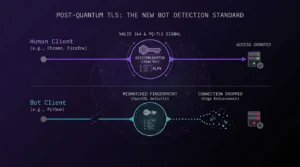
Post-Quantum TLS: The New Bot Detection Standard

Content delivery networks now evaluate the cryptographic handshake rather than relying on cookies or…

Post-Quantum TLS: The New Bot Detection Standard 7 Min Read
AL Alex onSeptember 15, 2026

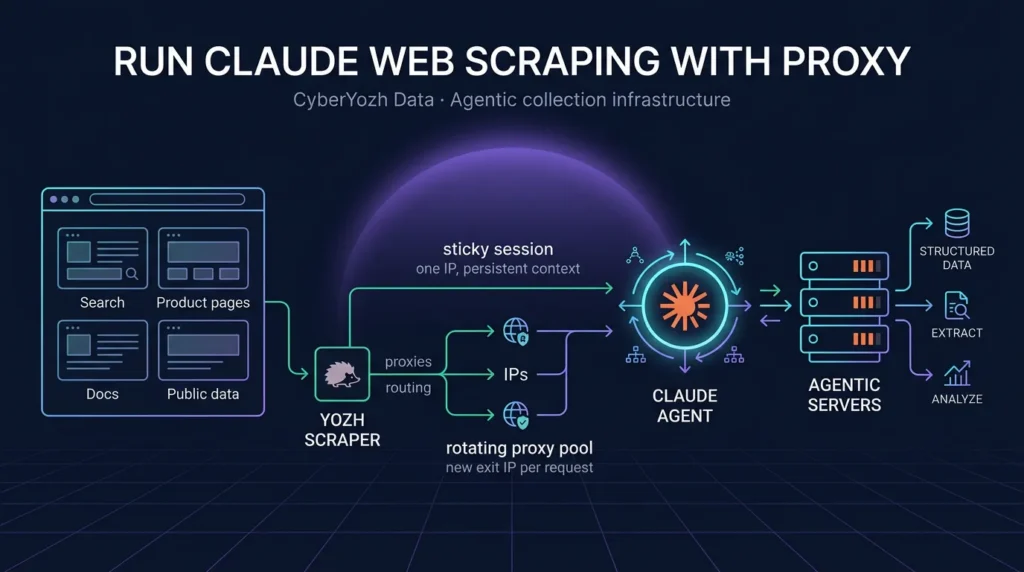
Run Claude Web Scraping with Proxy

Claude web scraping combines an AI assistant with a normal data-collection stack. However, Claude does not replace a browser, HTTP client, or proxy network. Instead, it helps define what data matters, generate and improve extraction logic, explain errors, and transform collected page content into a consistent format.  Key idea: Claude is the reasoning and extraction […]

Discover More
RO Roman onSeptember 10, 2026

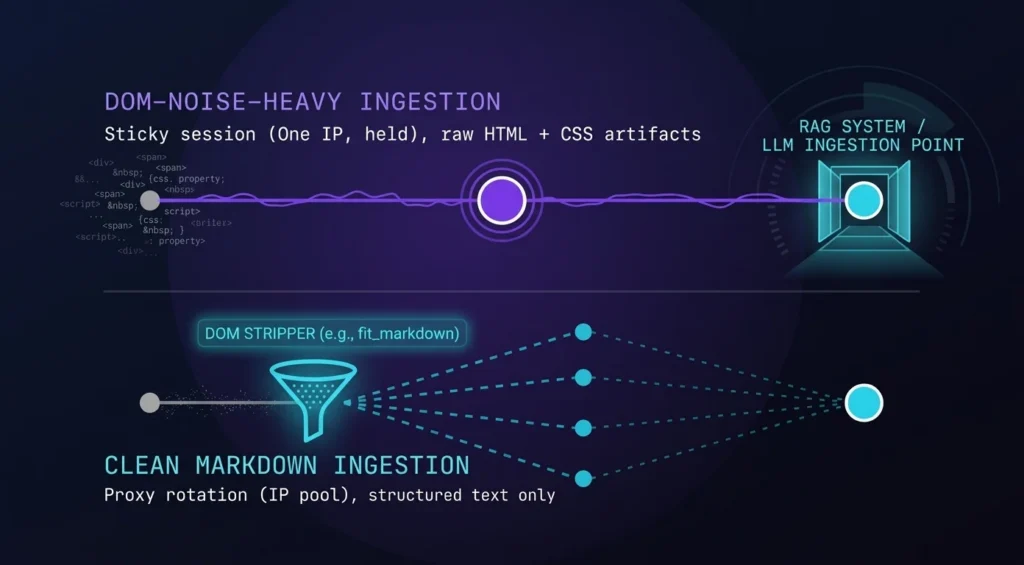
Feeding RAG Systems at Scale: How to Strip DOM Noise and Rotate Proxies for Clean LLM Ingestion

Targeting modern websites to train AI models breaks traditional data extraction pipelines. You point a headless browser at a dynamic product catalog. The target server instantly analyzes your TLS Client Hello signature. It checks your HTTP/2 frame sequence before sending a single byte of data. If your connection lacks a robust proxy ecosystem for web […]

Discover More
Connecting AI Agents to the Web: 99.8% Success with MCP Servers & Proxies (2026)
5 Min Read
RO Roman onAugust 26, 2026

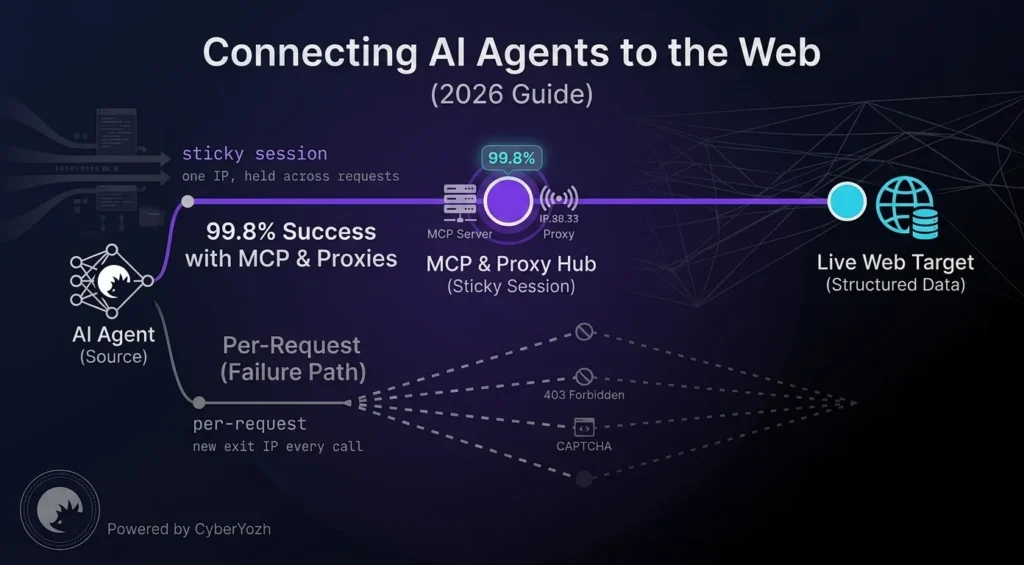
Connecting AI Agents to the Web: 99.8% Success with MCP Servers & Proxies (2026)

Quick Answer: The Model Context Protocol (MCP) acts as a universal bridge, allowing AI agents (like Claude Desktop or Cursor) to navigate the live web, render JavaScript, and extract structured data. However, to prevent IP bans and CAPTCHAs during automated web crawling, AI agents must route their requests through high-trust residential or mobile proxies that […]

Discover More
RO Roman onAugust 19, 2026

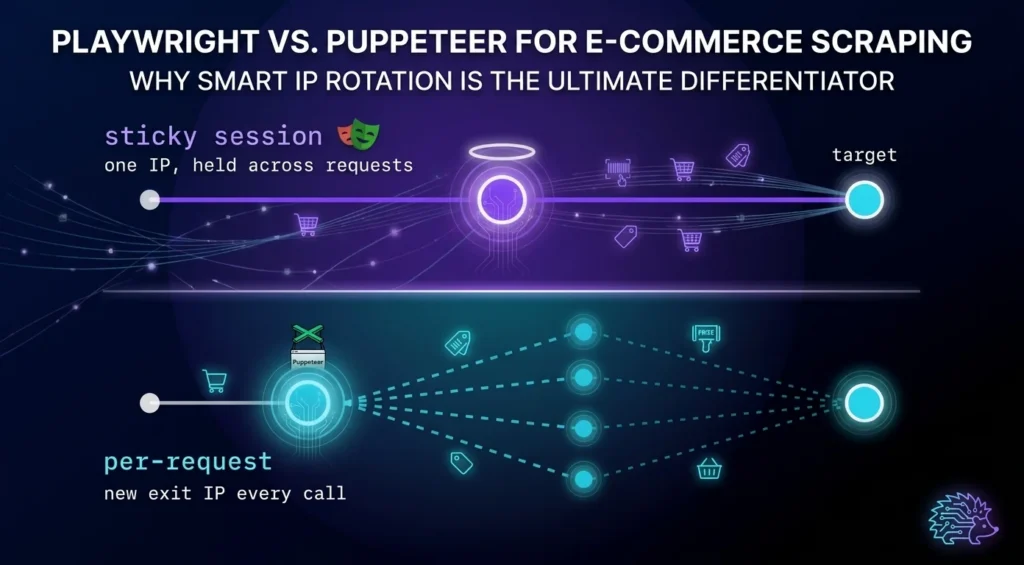
Playwright vs. Puppeteer for E-commerce Scraping: Why Smart IP Rotation is the Ultimate Differentiator

When evaluating Playwright vs Puppeteer for e-commerce scraping, engineers often obsess over execution speed and API syntax. However, in 2026, the landscape of data extraction has fundamentally shifted. Target websites deploy aggressive behavioral analysis, TLS fingerprinting, and dynamic DOM mutations. Building a pipeline that survives these defenses requires far more than picking a browser automation […]

Discover More
RO Roman onAugust 13, 2026

Resilient Scraping Pipelines: Introducing LLM Self-Healing Parsing in Yozh Scraper

Data extraction is the foundational layer of modern artificial intelligence development, market intelligence, and competitive analysis. However, building reliable data pipelines remains an engineering bottleneck. Target websites continuously deploy structural mutations, A/B testing, and dynamic obfuscation, causing rigid extraction scripts to fail. To resolve this paradigm of fragility, the web scraping ecosystem requires a fundamental […]

Discover More