GitHub
仅用一个下午就将我们内部的 Playwright 集群替换为 Yozh。MCP 端点直接接入我们的 Claude 代理——无需任何胶水代码,爬虫和数据提取工具便能正常运行。
一款用于数据采集和抓取的开源工具。只需输入一个 URL,即可爬取网站,并在页面加载时获取结构化数据。该工具可与 MCP 以及 Claude、Cursor 等工具配合使用,并为亚马逊、eBay 等电商平台提供了现成的预设方案。
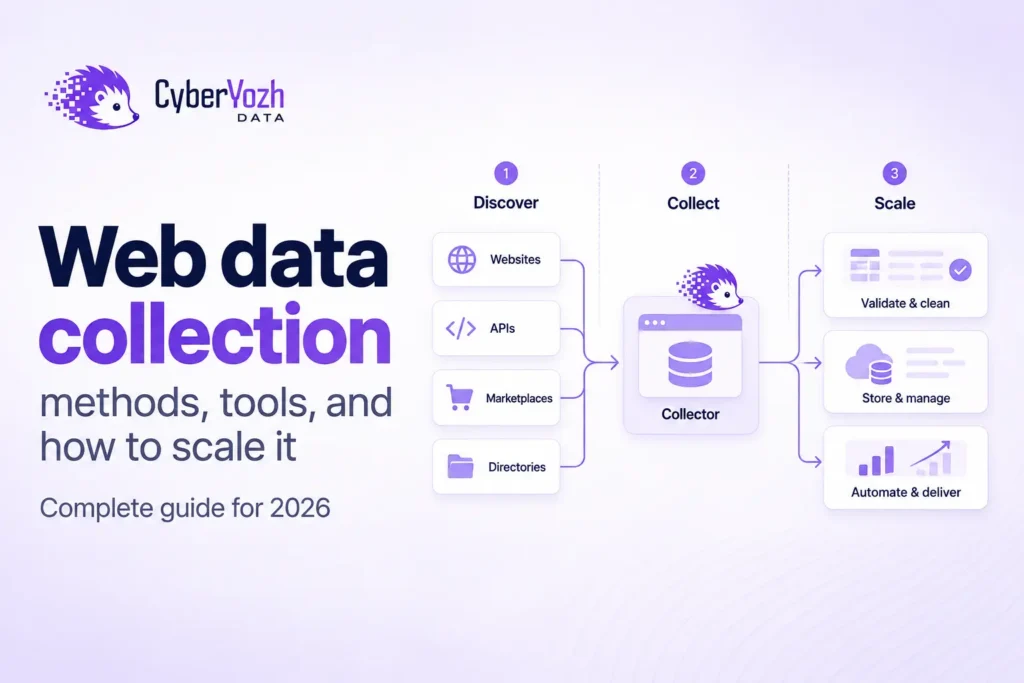
Yozh Crawler 会绘制整个网站的结构图,并在发现页面时立即对其进行处理。您只需运行一次,即可同时获得全面的覆盖范围和可用的结果,无需单独管理爬取和抓取步骤。它可直接集成到您现有的数据采集和抓取工作流中。
从一个 URL 开始,即可对整个网站进行爬取。页面将在一次运行中被发现并处理,因此无需额外步骤即可实现全面覆盖。
只需要链接吗?切换到探索模式,无需解析即可绘制网站地图。速度更快、更轻量,非常适合用于审计和结构检查。
根据请求头、位置和浏览器信号将请求与您的代理进行匹配。有助于确保不同地区之间的会话保持一致。
在一个请求中处理数百个URL。并行处理所有内容,并生成一个简洁的输出结果。
中止任务而不影响结果。让正在运行的页面完成,或在需要时立即中止所有任务。
直接与 Claude 和 Cursor 等工具对接。将数据抓取和爬虫功能整合到您现有的工作流程中。
亚马逊、eBay、沃尔玛、谷歌、谷歌购物、YouTube、领英、Bing、Yandex——只需传入来源名称和参数,即可获得规范化的响应。无需编写选择器。
某个网站发布了布局变更,而你的 CSS 选择器却返回了空结果?解析器会请求一个大语言模型(OpenAI / Anthropic / Gemini / OpenRouter)在运行时重新生成该选择器。处理流程继续运行。
需要我们尚未提供预设的网站吗?请描述需要提取的内容,并粘贴一个示例 URL — POST /api/v1/presets/generate 将返回一个可直接使用的预设 JSON 文件。
通过声明式 DSL(goto / fill / click / wait)登录一次,或粘贴导出的 Cookie。在每次抓取中复用该会话。对于 LinkedIn 预设等受限目标,此步骤必不可少。
在同一处设置您的工作流,并按需运行。一切清晰、有序且易于管理,无需额外工具。
可访问120多个国家的住宅、移动和数据中心代理。拥有超过5000万个IP地址,可用率达99.9%。支持指纹识别功能,可协调设备、浏览器和网络行为,从而确保会话稳定并实现更佳控制。
使用 CSS 选择器、XPath 或针对热门网站的自动检测功能。无需复杂配置,即可获取简洁、结构化的 JSON 数据。
一站式获取原始 HTML、截图和解析后的数据。您所需的一切,无需在不同工具之间切换。
只需点击一下,即可随时停止任务,并在抓取工具和爬虫之间切换。您的工作流程始终保持简单,且完全由您掌控。
将 Yozh Crawler 和 Yozh Scraper 连接到 Claude、Cursor 或任何 MCP 客户端。只需一次切换即可更换工具,无需额外编写代码。
Yozh Scraper 的所有功能均可作为代理程序的函数使用,包括数据抓取、批量运行和截图。
复制配置文件,重启客户端,即可完成设置。
Claude Desktop、Cursor、Cline 或自定义代理。
选择代理执行任务的方式,从单个页面到整批任务。
使用本地 MCP 服务器,或将其部署在您自己的基础设施上。
// ~/Library/Application Support/Claude/claude_desktop_config.json
{
  "mcpServers": {
    "yozh-scraper": {
      "type": "http",
      "url":  "http://localhost:8000/mcp"
    },
    "yozh-crawler": {
      "type": "http",
      "url":  "http://localhost:8001/mcp"
    }
  }
}
// Cursor → Settings → MCP → Add new MCP Server
{
  "mcpServers": {
    "yozh-scraper": {
      "type": "http",
      "url":  "http://localhost:8000/mcp"
    },
    "yozh-crawler": {
      "type": "http",
      "url":  "http://localhost:8001/mcp"
    }
  }
}
// Cline → MCP Servers → Edit cline_mcp_settings.json
{
  "mcpServers": {
    "yozh-scraper": {
      "type": "http",
      "url":  "http://localhost:8000/mcp",
      "disabled": false
    },
    "yozh-crawler": {
      "type": "http",
      "url":  "http://localhost:8001/mcp",
      "disabled": false
    }
  }
}
// Anthropic Messages API · MCP via Streamable HTTP
// Note: scraper must be reachable from Anthropic's servers (deploy publicly)
import Anthropic from "@anthropic-ai/sdk";

const response = await new Anthropic().messages.create({
  model: "claude-opus-4-8",
  mcp_servers: [
    { type: "url", url: "https://your-host/mcp", name: "yozh-scraper" },
    { type: "url", url: "https://your-host:8001/mcp", name: "yozh-crawler" }
  ],
  messages: [...]
});
Yozh Crawler 从一个 URL 开始,在整个网站中发现页面,并在页面加载时对其进行处理,一次运行即可为您提供完整的网站结构和可用的数据。
页面会在被发现并处理后立即显示。您可以直接从客户、代理或销售 pipeline 中访问,无需等待完整运行完成。
只需要链接吗?无需解析即可生成网站地图。在结构检查和审核方面,这种方式更快、更经济。
安全地停止任务。让正在运行的页面完成处理,或在需要时立即停止所有操作。
只需一个切换开关,即可在爬虫和抓取工具之间切换。您的代理会根据每项任务选用合适的工具。
实时查看网站结构的构建过程。无需离开仪表盘,即可逐页跟踪进度。
| URL | Parent | Depth | Status | Took |
|---|
爬虫负责查找网页,抓取工具负责处理这些网页,而您的AI代理则利用处理结果——该工具专为初学者和专家设计。
查找所有 URL
提取为 JSON
分析并决定
在同一处跟踪竞争对手的产品目录、价格和产品详情。发现自身产品列表中的缺口,并更快地应对市场变化。
自动追踪各电商平台的价格变动。设置提醒,当价格发生变动时,通过Telegram或Slack接收通知。
从公开来源收集干净、结构化的数据集,可直接用于分析或模型训练。专为大规模、可靠的数据采集而设计。
区域设置、货币、选择器及反机器人处理——均已配置完毕。选择一个预设,查看会提取哪些内容。
All fields below are extracted automatically — no selectors to write.
请在 GitHub 上提交问题,或贡献您自己的预设——我们将在一周内审核拉取请求。
三种类型,六种配置。可根据工作需求、速度和预算进行选择。
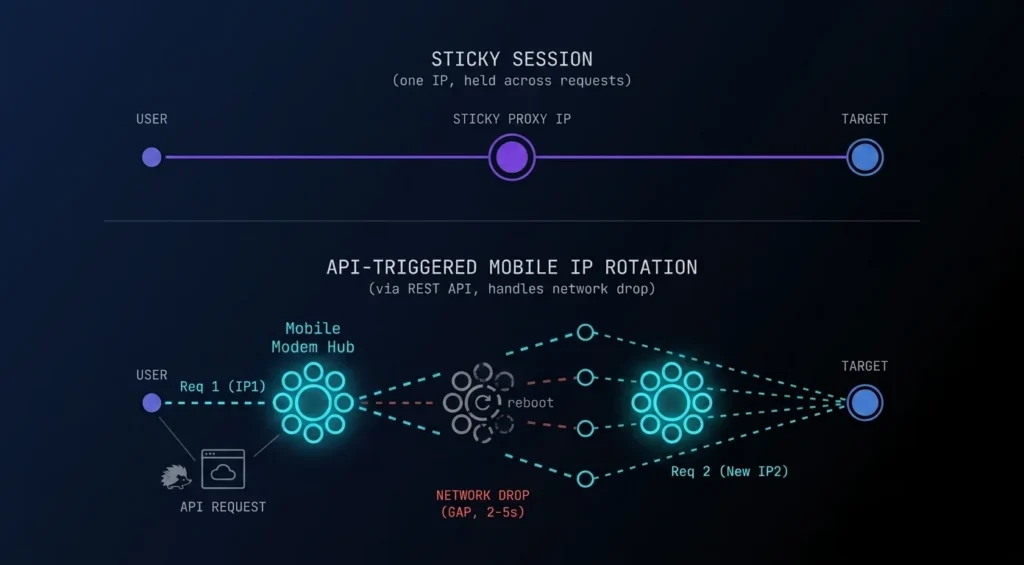
连接运营商网络的真实移动设备。具备最高可信度等级,并配备严格的反机器人系统。
个人设备,通过 API 手动轮换 IP 地址
一台设备,多名用户
每个 IP 地址都来自连接到主要移动运营商网络的真实智能手机或 LTE/5G 调制解调器。该 IP 地址由数千名普通用户共享,因此封锁它将导致真实用户无法访问——这也是反机器人系统最信任移动 IP 地址的原因。
来自120多个国家真实家庭互联网用户的IP地址。提供5000多万个IP地址,在可信度与成本之间实现了良好的平衡。
真正的路由器,整个租赁期间均提供固定IP地址
1亿+ IP地址池,可通过定时器或按请求自动轮换
住宅IP地址来源于真实的家庭宽带用户,这些用户通过一个透明的自愿加入网络,同意在获得补偿的前提下共享带宽。他们的网络连接看起来与任何其他家庭用户无异——因为他们本身就是家庭用户。
最高速度,最低成本。全球各数据中心拥有200多万个IP地址。
为您分配一个IP地址,流量不限
共享池:适用于简单任务的经济实惠之选
这些 IP 地址托管在数据中心内,未与家庭或移动用户连接。它们比家庭 IP 地址更便宜、速度更快,但反机器人系统可能会将其识别为非人类来源,因此请仅在信任度要求不高的场景中使用。
开源代码仅仅是一个起点。数据的收集方式和代理服务器的获取方式同样重要。这些是我们实际遵循的标准,而非纸上谈兵的声明。
我们开发的是工具,而不是漏洞。Yozh Scraper 的设计初衷是确保对合法公开数据的抓取可靠进行——而非破坏本应保持封闭的内容。
住宅IP的来源是检验每家代理服务商诚信度的试金石。以下是我们IP的来源——明确说明如下:
如果有人滥用我们的基础设施来伤害他人,我们希望及时了解情况——并在事态恶化之前采取行动。
如果某个用例涉及滥用或造成伤害,我们的工具并不适用于此类情况。我们优先考虑负责任的使用,而非客户增长。
如果某个用例需要隐藏身份来伤害他人,那么我们的工具绝不会被用于此目的。绝不。与其违背原则,我们宁可失去这位客户。
明确的规则,指导我们的运营方式,涵盖从数据收集到代理采购以及平台使用等各个方面。这些是我们团队实际遵循的政策,而非摘要。
"CyberYozh stands out as a powerful platform for affiliates and arbitrage teams, combining reliable proxy infrastructure, identity tools, and strong support in one ecosystem."
"CyberYozh App enables businesses to launch, test, and operate digital products across more than 30 countries through a scalable infrastructure built for global connectivity, verification, and digital operations."
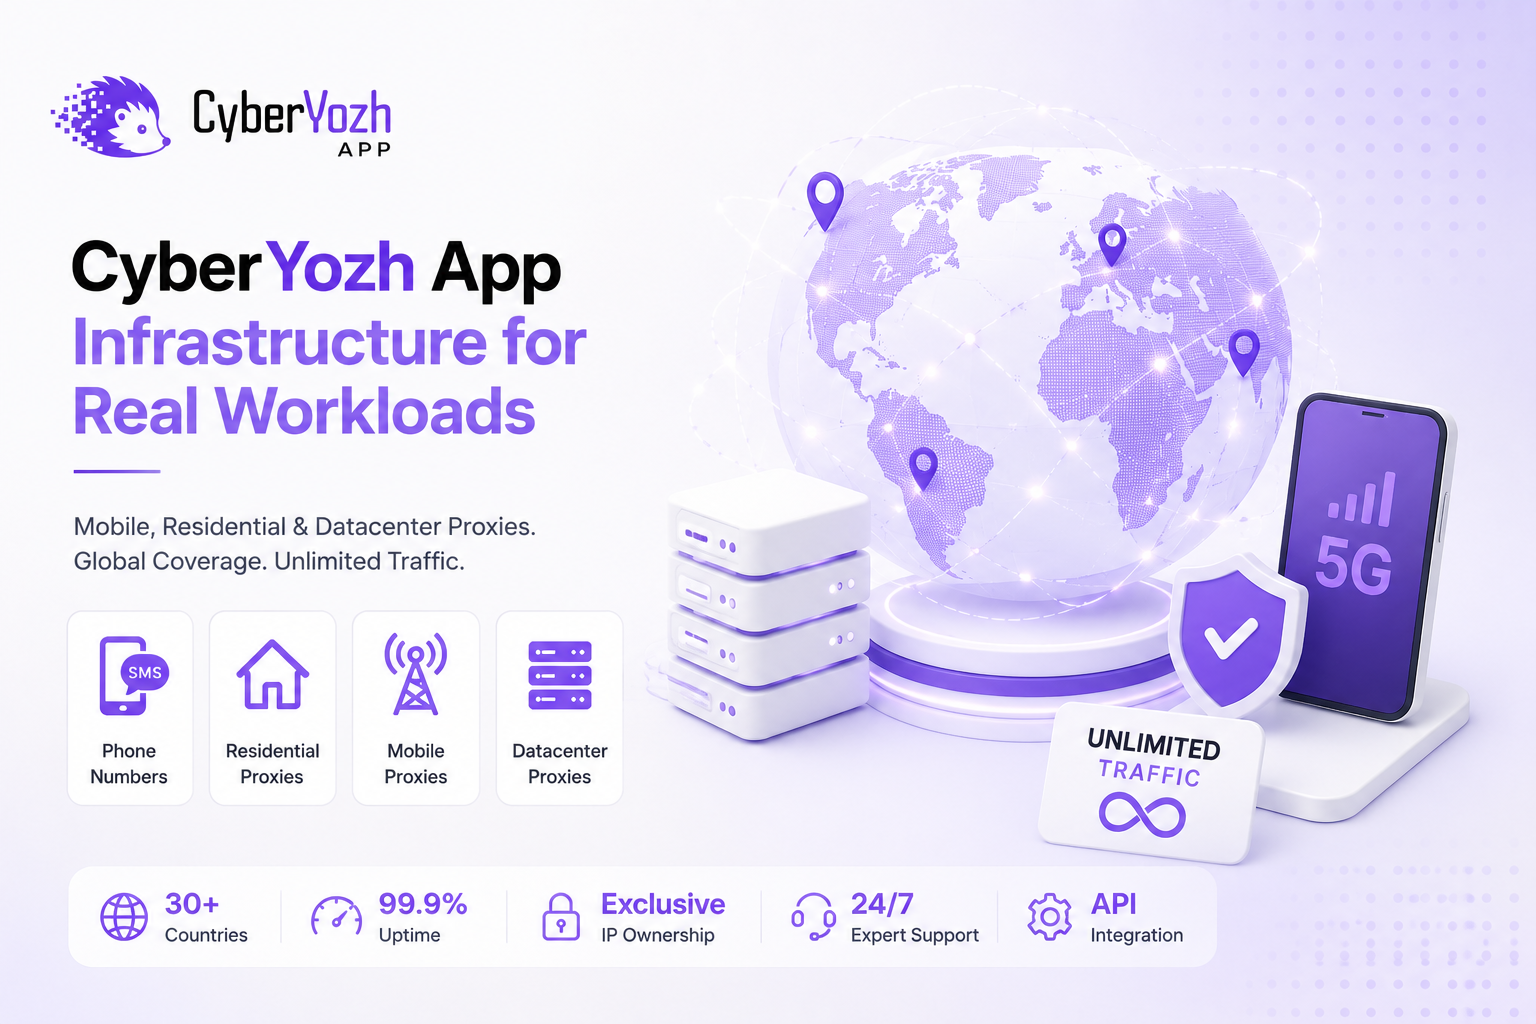
"Built for organizations that rely on proxies every day, CyberYozh App delivers infrastructure designed for stability, scalability, and high-volume workloads rather than one-off sessions."
使用 Yozh 进行开发的用户怎么说
仅用一个下午就将我们内部的 Playwright 集群替换为 Yozh。MCP 端点直接接入我们的 Claude 代理——无需任何胶水代码,爬虫和数据提取工具便能正常运行。
预设系统是其杀手级功能。我们传入源名称,就能得到干净的 JSON 数据;其自动修复功能甚至在我们察觉之前就发现了亚马逊的两次布局变更。
终于出现了一个将代理和会话视为第一类对象的开源爬虫工具。我们将其部署在合作伙伴门户网站的登录墙后方——会话能够保持持久性,且跨区域的爬取结果始终保持一致。
通过 MCP 将其连接到 Cursor 后,我的代理现在可以在任务进行中实时提取网页数据。通过 SSE 进行的流式爬取,正是代理工作流所缺失的功能。
为了节省成本,我们放弃了付费的数据抓取 API,并做好了性能下降的准备——结果却事与愿违。现在采用自托管模式,无需按请求付费,而且输出数据结构比我们以前付费使用的还要简洁。
Yozh Scraper 是一个开源项目,所有更新均可在 GitHub 上查看。以下是最新亮点。
container selector; everydevice=legacy_wap — a feature-phone identity that unlocks Google's no-JSresolve_redirects — names extracted fields whose values are the page'sozon_search, ozon_product, mobile_de_search,<name>_chromium and <name>_camoufox (e.g. google_search_chromium, yandex_search_camoufox). A request names the exact variant it wants; each preset carries its own browser_engine.LOG_FORMAT=json (default text).EGRESS_ALLOW_HOSTS allowlist (empty by default) and an EGRESS_TRANSPORT_GUARD toggle (on by default).google_search, google_shopping, amazon_product, amazon_search, bing_search, ebay_search, linkedin_profile, walmart_product, yandex_search, youtube_video) are replaced by their per-engine variants. A request using a bare old name now returns 404 preset_not_found; append the engine suffix (_chromium, or _camoufox for the two anti-bot targets yandex_search and walmart_product).GET /api/v1/proxies/available and the entire /api/v2/prem-proxies/* catalog now require SERVICE_TOKEN and fail closed (503 when the token is unconfigured, 401 without it). Any consumer of these endpoints must send the X-Service-Token header; deploy the consumer first, or its calls degrade (for the proxy geo catalog, silently).unreadable_slots. A job with one corrupt or schema-skewed result slot now returns its other pages (HTTP 200) and names the bad slot, instead of the whole job failing with a 500 and becoming un-cancellable until its TTL expires.navigator, and Client-Hints (Sec-CH-UA) as the main fetch path, via a shared page-preparation helper. A credentialed login no longer submits a contradictory fingerprint (previously a macOS GPU and a HeadlessChrome Client-Hint under a Windows user agent).all / attr / post_process and required fields, and it is graded against the original contract — so a heal that returns a bare string where a coerced list belongs is no longer counted as a recovery. It also never heals from a transient 5xx error page. This closes a class of silent preset corruption.user:pass; a shared redactor masks proxy URLs while preserving host:port for diagnostics.litellm is bounded <1.98: 1.98.0 imports NotRequired from typing unguarded and fails to import on the Python 3.10 this project targets, so a fresh install or image build would produce a container that cannot start.HOST_GPU_VENDOR). Without it the restored context reported a generic SwiftShader/ANGLE software-renderer string, itself an automation tell.--enable-unsafe-swiftshader, gated by the new SOFTWARE_WEBGL setting (default on, Chromium-only; revertible by env without a code change).data.cyberyozh.pro) with per-service pages for the scraper and crawler.redis and scraper-worker services (both are already in docker-compose.yml). Scale capacity with docker compose up -d --scale scraper-worker=N.POST /scrape/page and /scrape/pages can now return 503 queue_full when the Redis stream depth exceeds QUEUE_MAXSIZE (previously the in-memory queue was unbounded).JOB_TIMEOUT_MS → use PAGE_TASK_TIMEOUT_S; JOB_RESULT_MAX → eviction is now a native Redis TTL (JOB_RESULT_TTL_S); JOBS_ENABLED → the queue is always on.REDIS_URL, PAGE_TASK_TIMEOUT_S, LOGIN_TASK_TIMEOUT_S, LOGIN_RESULT_GRACE_S, RECLAIM_IDLE_S, JOB_RESULT_TTL_S, BROWSER_MAX_PAGES, BROWSER_IDLE_SHUTDOWN_S, WARMUP_DWELL_MS.web-scraper container only enqueues page tasks and reads results; browsers run in separate, horizontally scalable scraper-worker containers.只需三条命令,即可获得一个支持 HTTP 和 MCP 端点的可运行抓取工具 + 爬虫。
git clone https://github.com/\
  CyberYozh-data/yozh-scraper
cd yozh-scraper
cp .env.example .env
docker compose up --build
curl -X POST localhost:8000/api/v1/scrape/page \
  -H 'Content-Type: application/json' \
  -d '{"url":"https://example.com"}'
所有收到的消息都会由真人逐一阅读。请选择适合您的渠道——Telegram 的响应最快。
Yozh Crawler + Scraper 是免费的。永远免费。如果它对您有帮助,请给我们点个星——每一颗星都至关重要。
Yozh Crawler + Scraper 根据 MIT 许可证发布。请随意使用、分叉和基于它进行开发。